
Description
PowerEdge XE9712 (GB300 NVL72)
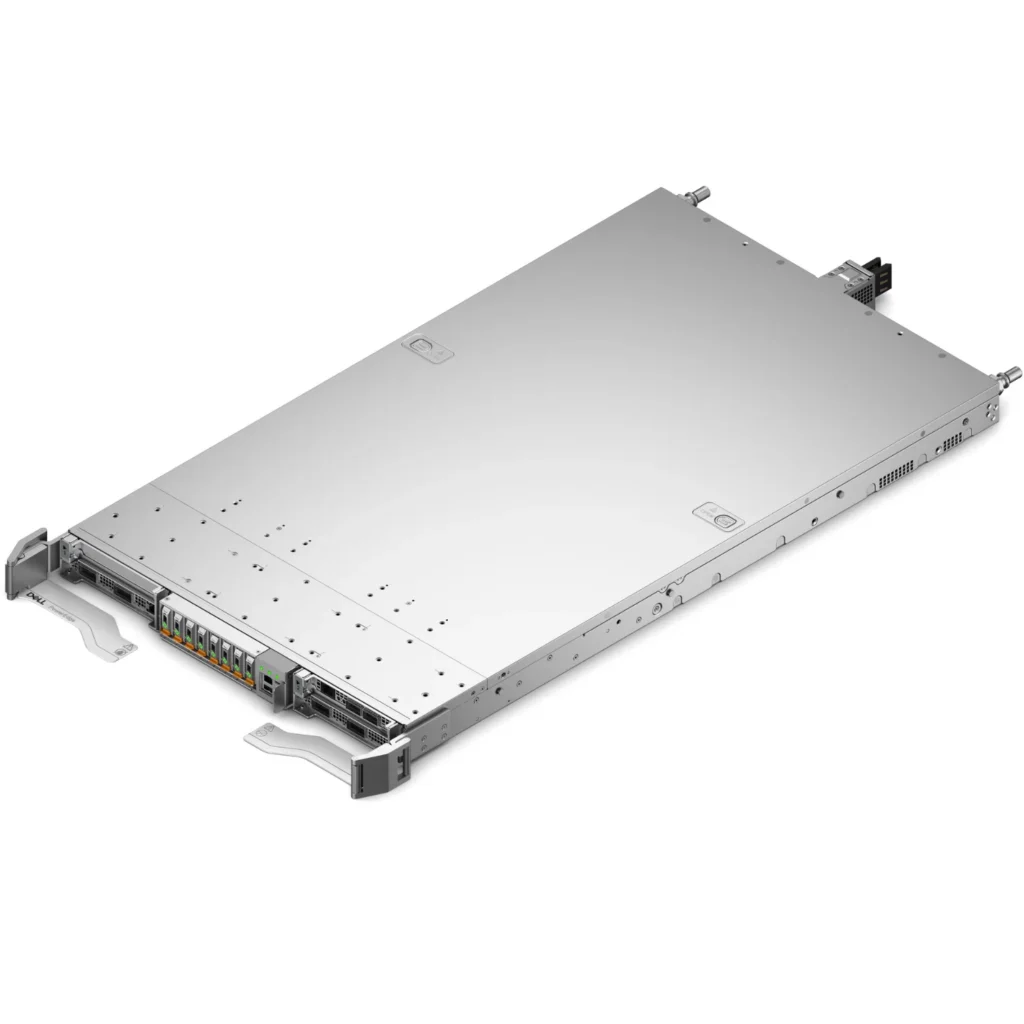
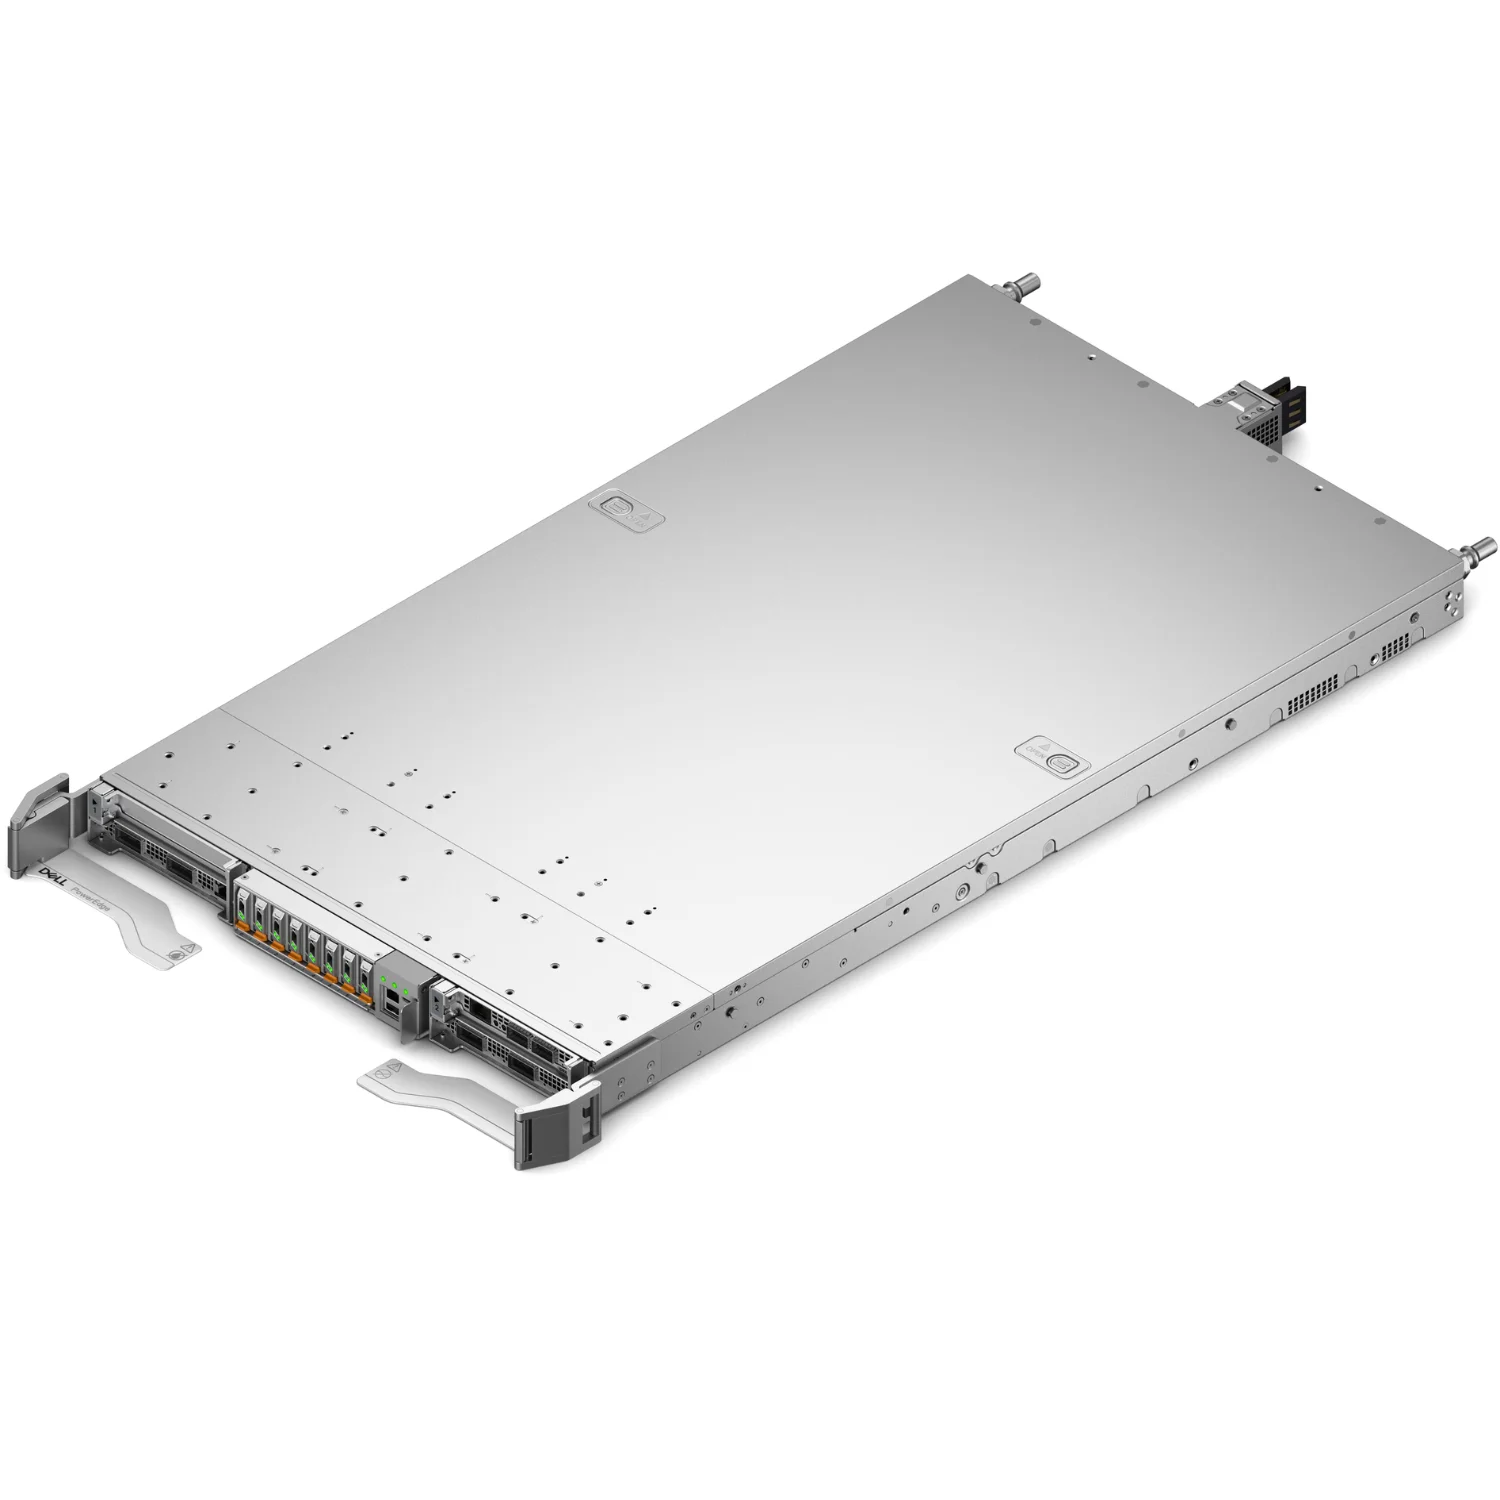
The Dell PowerEdge XE9712 (GB300 NVL72) is an enterprise AI supercomputing platform designed for organizations that need massive computational throughput, trillion-parameter model training, and real-time generative AI inferencing. Operating as a liquid-cooled rack-scale system within the Dell Integrated Rack IR9048, it packs 1U compute sleds running NVIDIA GB300 NVL72 architecture. It supports high-density AI workloads while providing dedicated interfaces for management, storage, telemetry, and high-speed network fabrics.
The platform combines Dell Technologies system architecture with custom-built NVIDIA hardware. This design allows enterprises to execute massive AI models, process complex multimodal datasets, and offload computational bottlenecks from traditional data center infrastructure. Dell positions the PowerEdge XE9712 for liquid-cooled AI factory scale and extreme compute density.
Key Features of PowerEdge XE9712 (GB300 NVL72)
Rack-Scale NVLink Fabric Processing
The PowerEdge XE9712 processes extreme workloads using a unified 72-GPU NVLink domain. The 5th-generation NVLink switch fabric enables all 72 GPUs inside the rack to communicate seamlessly, allowing developers to run multi-trillion parameter LLMs as if operating on a single massive GPU accelerator.
Direct Liquid Cooling Architecture
Extreme AI compute densities generate significant thermal output. The PowerEdge XE9712 offloads 100% of GPU and CPU thermal heat via Direct Liquid Cooling (DLC) cold plates coupled with liquid-to-liquid Coolant Distribution Units (CDUs). This design reduces cooling power consumption while eliminating air-cooling throughput limitations.
Ultra-High Speed Storage & Network Connectivity
The platform provides up to eight front-accessible EDSFF E1.S NVMe Gen5 drive bays per compute sled, directly connected to NVIDIA ConnectX-8 networking cards. It supports both Ethernet (Spectrum-X) and InfiniBand (Quantum-X800) fabrics at full line rate, enabling accelerated GPUDirect storage transfers and multi-rack expansion.
Rack-Scale Power & High Availability
The platform relies on a 54 VDC busbar architecture fed by redundant 33 kW Power Shelves (PS33). Dedicated capacitance shelves handle short-term power spikes during intensive AI training loops. The system supports hot-swapping of compute sleds, liquid connectors, and network transceivers to maintain high uptime in production environments.
Integrated Hardware Management
The PowerEdge XE9712 includes an ASPEED AST2600 Baseboard Management Controller (BMC) paired with an NVIDIA Hardware Management Console (HMC). System administrators can monitor thermal sensors, power consumption, leak detection systems, and hardware health remotely across the entire rack enclosure.
Capabilities
- AI Model Training: The platform executes large-scale pre-training for massive foundation and domain-specific AI models.
- Real-Time Inferencing: PowerEdge XE9712 can host trillion-parameter LLMs entirely in unified memory to deliver ultra-low-latency real-time responses.
- Multimodal Workload Processing: Hardware acceleration enables concurrent handling of text, image, video, and synthetic data generation tasks.
- Scalable AI Infrastructure: Organizations can use the platform as an individual rack or scale out across multiple nodes to form enterprise AI factories.
- Thermal & Power Optimization: Dell’s liquid-cooled design uses custom CDU loops and high-efficiency power shelves to maximize performance-per-watt efficiency.
- Centralized Fleet Management: PowerEdge uses Dell OpenManage and iDRAC integration to provide control, telemetry, and lifecycle management across supercomputing clusters.
Key Specifications
| Feature / Specification | Details |
| Series | Dell PowerEdge XE Series |
| Rack Architecture | Dell Integrated Rack IR9048 (48U ORv3 / 19-inch) |
| Compute Sled Form Factor | 1U rack-mount compute sled |
| Processor | 2 × NVIDIA Grace CPUs per sled (36 total per rack / 2,592 cores) |
| GPU Accelerators | 4 × NVIDIA Blackwell Ultra GPUs per sled (72 total per rack) |
| GPU Memory | 288 GB HBM3e per GPU (Up to ~21 TB HBM3e total per rack) |
| CPU Memory | Up to 480 GB LPDDR5X ECC per CPU (Up to ~17 TB total per rack) |
| Storage Bays | Up to 8 × EDSFF E1.S NVMe Gen5 hot-swap bays per sled |
| Boot Storage | 1 × M.2 NVMe Gen4 SSD riser |
| Interconnect | 5th Gen NVLink (900 GB/s CPU-to-GPU, 130 TB/s aggregate rack bandwidth) |
| High-Speed Networking | NVIDIA ConnectX-8 SuperNICs (4 × 800 Gb/s OSFP per sled) |
| Management Port | Dedicated iDRAC RJ45 / 1 GbE LOM / ASPEED AST2600 BMC |
| Power Architecture | 54 VDC Busbar via 33 kW PS33 Power Shelves (6 × 5500 W AC PSUs) |
| Cooling System | Direct Liquid Cooling (DLC) with liquid-to-liquid CDU support |
Common Use Cases
The PowerEdge XE9712 (GB300 NVL72) fits AI supercomputing environments that require high-density GPU acceleration, unified high-bandwidth memory, and liquid-cooled data center deployment. Organizations can use it in enterprise AI facilities to run large language models, autonomous system training, structural biology research, and high-frequency financial modeling. It integrates directly with high-performance storage systems and modern 800G optical networking infrastructure.
Real-World Deployment Scenarios
- Large Language Model (LLM) Pre-Training: Train multi-billion and trillion-parameter foundation models across a unified 72-GPU NVLink domain.
- Generative AI & Multimodal Pipelines: Process high-resolution image synthesis, video generation, and voice-to-text translation workloads concurrently.
- Enterprise Fine-Tuning & Domain Adaptation: Rapidly adapt open-source foundation models using parameter-efficient fine-tuning (PEFT/LoRA) techniques.
- AI Factory Deployments: Chain multiple liquid-cooled XE9712 racks together via InfiniBand or Ethernet fabrics to build scalable AI clusters.
- High-Performance Computing (HPC) & Simulation: Execute complex physics simulations, molecular modeling, and scientific calculations requiring high FP64/FP32 precision.
- Real-Time Financial & Analytics Engines: Perform instant risk calculations, algorithmic trading strategy testing, and fraud detection on massive data streams.
Why Choose Netmate IT for PowerEdge XE9712?
Netmate IT helps organizations evaluate and deploy advanced Dell Technologies supercomputing platforms based on their compute, cooling, and network requirements. For the PowerEdge XE9712 (GB300 NVL72), Netmate assists teams in sizing liquid cooling infrastructure, planning high-density power delivery, integrating high-speed networking fabrics, and configuring deployment services. The goal is to provide an efficient Dell AI solution tailored to the enterprise’s computational demands, thermal limits, and infrastructure capacity.
Frequently Asked Questions
What is the Dell PowerEdge XE9712 (GB300 NVL72)?
The PowerEdge XE9712 is a liquid-cooled rack-scale AI server platform designed by Dell Technologies. It integrates up to 18 1U compute sleds featuring 36 NVIDIA Grace CPUs and 72 NVIDIA Blackwell Ultra GPUs connected into a single NVLink domain within a 48U rack frame.
What is the difference between individual AI servers and the XE9712 NVL72 system?
Unlike standalone PCIe or SXM server nodes connected over standard network cables, the XE9712 NVL72 connects all 72 GPUs inside the rack using high-speed NVLink switches. This treats the entire rack as a single unified super-accelerator with up to 21 TB of HBM3e memory operating at 130 TB/s aggregate interconnect bandwidth.
How much GPU memory does the PowerEdge XE9712 support?
Each NVIDIA Blackwell Ultra GPU contains 288 GB of HBM3e memory. Across a fully populated rack of 72 GPUs, the system delivers up to 21 TB of high-bandwidth memory alongside up to 17 TB of LPDDR5X CPU system memory.
What cooling infrastructure is required for the PowerEdge XE9712?
The PowerEdge XE9712 relies on Direct Liquid Cooling (DLC). Coolant is routed directly across cold plates covering the Grace CPUs, Blackwell Ultra GPUs, and NVLink switches, connecting to in-rack or in-row Coolant Distribution Units (CDUs) to manage heat dissipation.
Who should deploy the PowerEdge XE9712 platform?
The platform fits enterprise AI research centers, hyperscalers, cloud service providers, and large institutions that require high-density compute capacity for training complex generative AI models, running real-time inference, and operating scalable AI factories.
Reviews
There are no reviews yet.